Intempt
All free tools
Analytics

Free A/B test significance calculator.

Check if your A/B test result is statistically significant. Paste control and variant numbers to get p-value, confidence interval, and the sample size you still need. In Blu, the Experimentation Lead agent fixes sample size, a guardrail metric, and a stopping rule before a test ships, so underpowered ones don't.

How to use the A/B test significance calculator

It takes three steps and every output renders on this page so you can copy or export it right away.

Enter visitors and conversions

Add the visitor and conversion counts for your control and your variant. Manual counts from any tool are fine.

Check significance

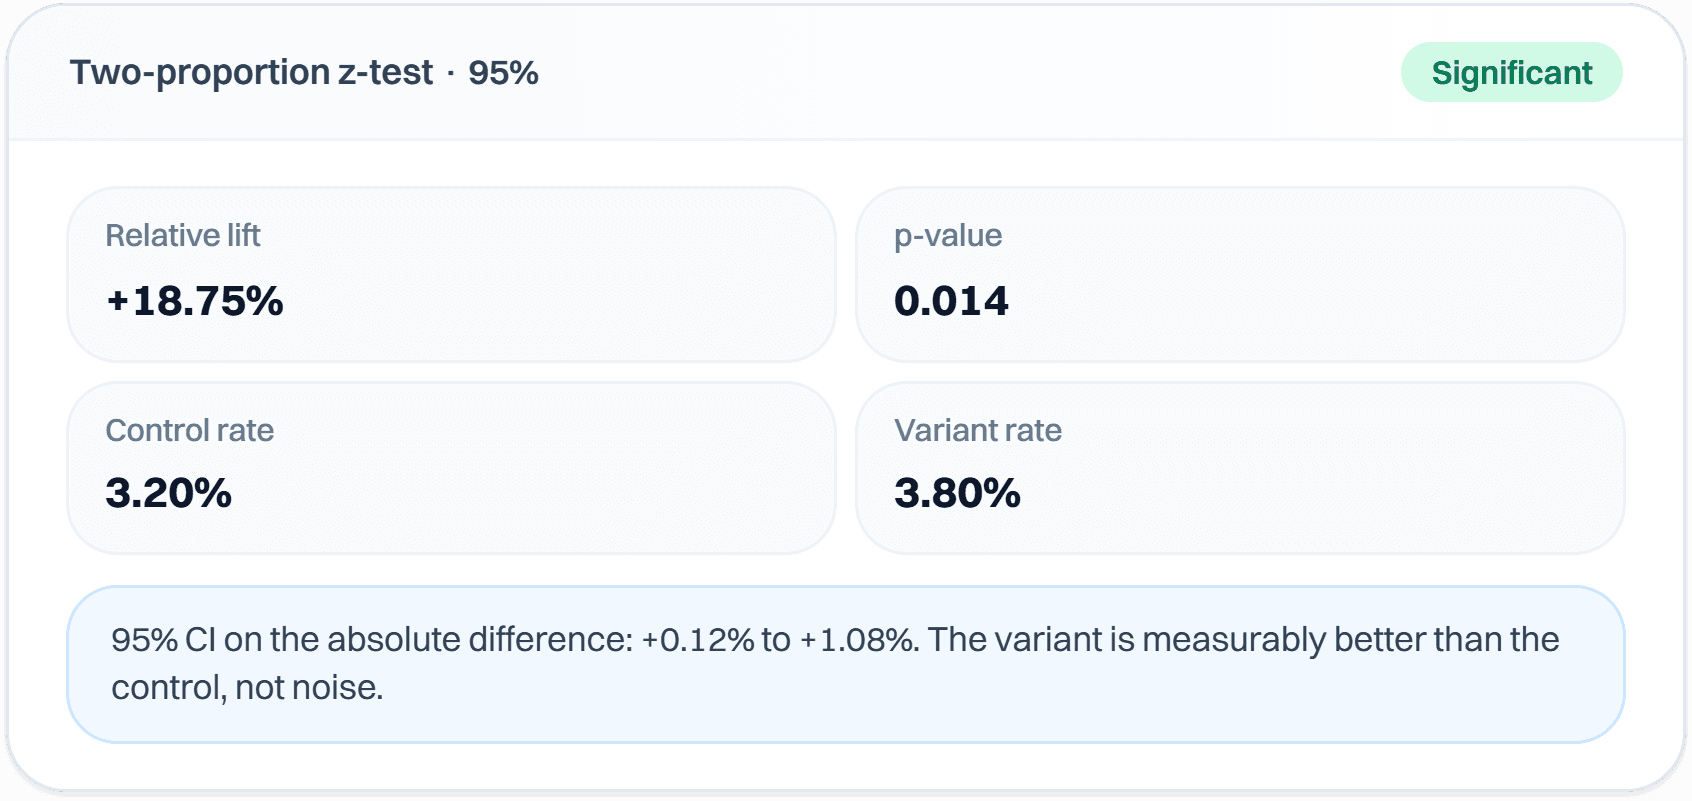
The A/B test significance calculator returns the p-value, relative lift, both conversion rates, and a 95% confidence interval on the difference.

Open it inside Intempt

Push the parameters into an experiment inside Intempt so the Experimentation Lead agent runs the test with a real hypothesis, guardrails, and a defined exit rule.

Use in Claude

Blu Agent

Who it's for

  • Marketing and growth teams deciding whether to call an A/B test
  • Anyone who wants the significance math without a spreadsheet or a Bayesian black box

What's in the download

  • SKILL.md - The exact two-proportion z-test math (p-value, CI, sample size, days-to-significance) from the browser tool, plus instructions to check for a connected analytics/CRM MCP first, falling back to pasted numbers.

How to install it

claude.ai or Claude Desktop
Upload as a zip in Capabilities
Paid plan
  1. Open Settings, then Capabilities
  2. Turn on code execution if it isn't already on
  3. Upload the .zip you downloaded
Requires a Pro, Max, Team, or Enterprise plan. Not available on the Free plan.
Claude Code
Drop the folder, it auto-loads
Any plan
  1. Unzip the download
  2. Drop the folder into ~/.claude/skills/ (or .claude/skills/ in a project)
  3. Claude Code finds it automatically
$ ls ~/.claude/skills/
your-new-skill/

What you need

  • Claude Desktop or claude.ai (Pro, Max, Team, or Enterprise for claude.ai upload)
  • Claude Code: no plan restriction
  • An analytics or CRM MCP connector is optional - pasted numbers work without one

Try it with

  • “Use the ab-test-calculator skill to check if my checkout redesign test is significant”
  • “Pull my latest experiment numbers and tell me if I can call a winner yet”

Prefer an instant answer? Run it now above.

What you get from the A/B test significance calculator

What it does on this page, and what it does inside Intempt.

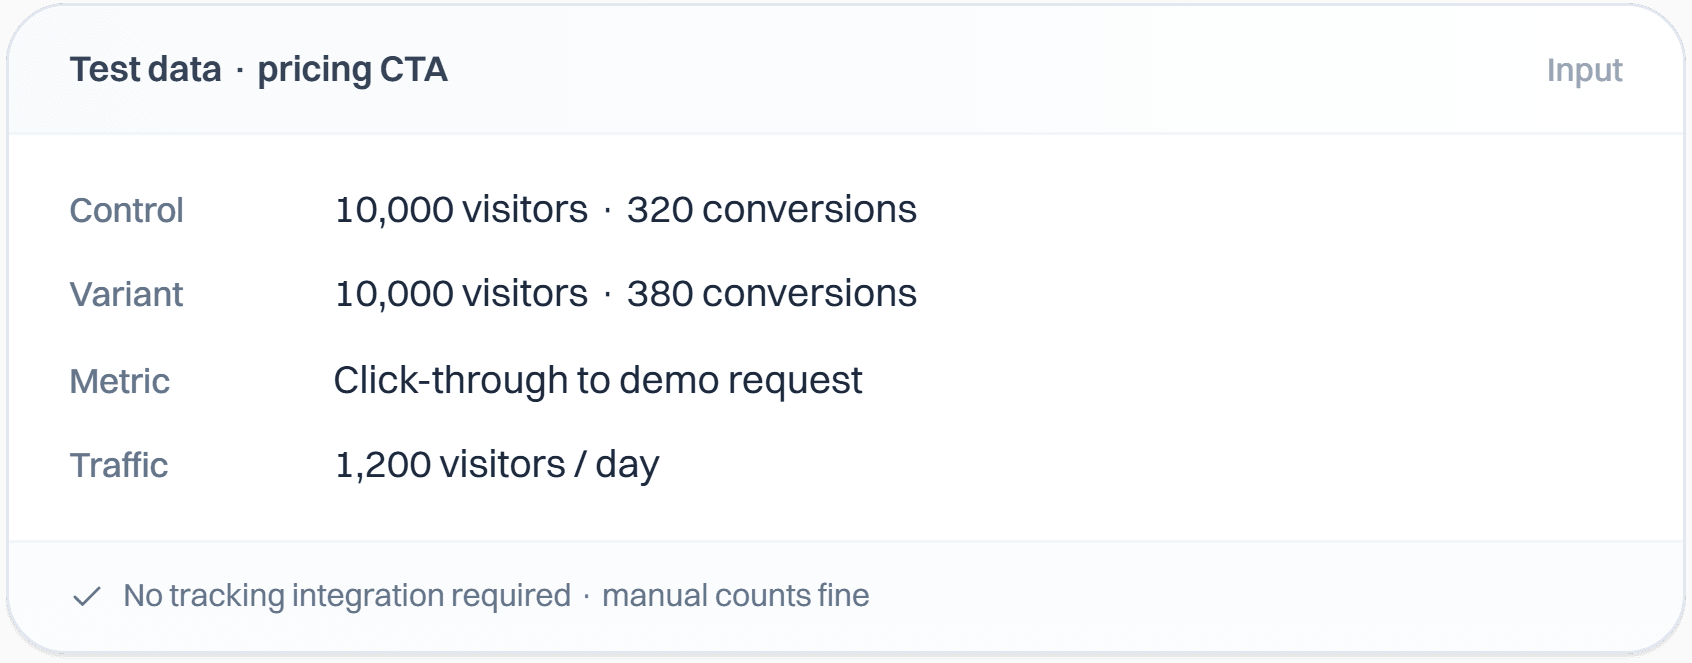
Four numbers in, no tracking setup needed

  • Enter visitors and conversions for the control and the variant
  • Works with any rate: signups, clicks, demo requests, or bounces
  • Counts from a spreadsheet or a dashboard export are fine
A test data card for a pricing CTA listing control and variant visitors, conversions, the metric, and daily traffic.

A statistical significance calculator that shows its math

  • Runs a two-tailed, two-proportion z-test at 95% confidence
  • Reports relative lift, the p-value, and both conversion rates
  • Adds the 95% confidence interval on the absolute difference
A two-proportion z-test result marked significant, showing relative lift, p-value, both conversion rates, and the confidence interval.

Ship every experiment with a defined hypothesis

  • Hypothesis, primary metric, guardrail, and exit rule are all set upfront
  • Locked in before a single pixel moves
  • No test ships on gut feel
A/B test setup panel with hypothesis, primary metric, and guardrail defined before launch.

Watch guardrails while the test runs

  • You watch the primary metric and every guardrail side by side
  • If a variant lifts one metric while it wrecks another, you'll catch it
  • The kill switch trips on its own - nobody has to be watching
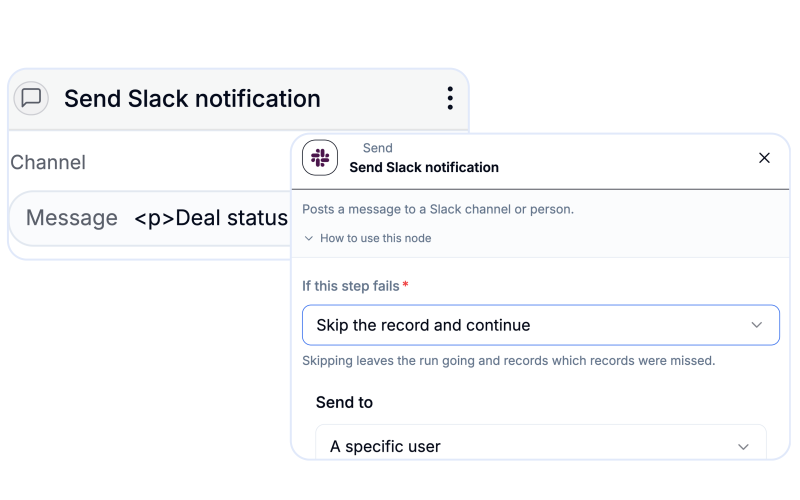
Automatic alert firing when a guardrail metric is crossed mid-test.

See it work on your own output.

Start free

Questions about theA/B test significance calculator.

Yes. Sign up for the free Intempt plan, then run calculations on this page free 10 times a day, and up to 10 times a day across all the tools. Designing experiments, running them against real users, and reading confidence intervals sit inside the free Intempt plan.

Teams love it

They stopped stitching tools andhired one system.

StockInvest

Acquisition and retention are one connected motion. Personalizing the path before signup only pays off when the same system carries the user through onboarding afterward.

Anonymous traffic was not turning into registered users, and acquisition and retention were run as two separate problems. We ran Experiences on the anonymous visitor flow to put the right content and CTAs in front of each visitor, then handed new signups to automated Journeys for onboarding and deeper engagement.

455,396

users instrumented
Read the full research
FieldsUSA

Judge experiments on revenue per visitor instead of conversion rate. A variant can win on conversions and still lose on revenue, and repeat buying only shows up when the whole journey is in one view.

High-intent shoppers browsed a large, specialized outdoor catalog, and browsing, product interest and purchase history sat in different places. We unified them into one customer view, then ran real-time personalization, intent-based segmentation and timely follow-ups on top of it, judging experiments on revenue per visitor.

Read the full research
Hoperfy

Build the pipeline on observed signals. When follow-ups trigger on intent, the team spends its time on the users who are genuinely engaging.

Static lead lists and timeline-based follow-ups were hiding who was actually engaging. We ran a signal-led outbound pipeline where follow-ups fire on real behavior: outbound replies, onboarding progress and product usage.

Read the full research

Run the experiment live.

Hypothesis and stopping rule fixed before launch, with no analyst to staff. Guardrail metrics come in on the Org plan.

Start for free